- Company
- dotData
- Industry
- Enterprise AI, AutoML platform
- Role
- Sr Product Designer
- Scope
- Research, prototyping, visualization, interaction design
- Team
- 1 PM, 4 Engineers, 1 Data Scientist
- Timeline
- 6 months
Simplifying AutoML setup for business analysts
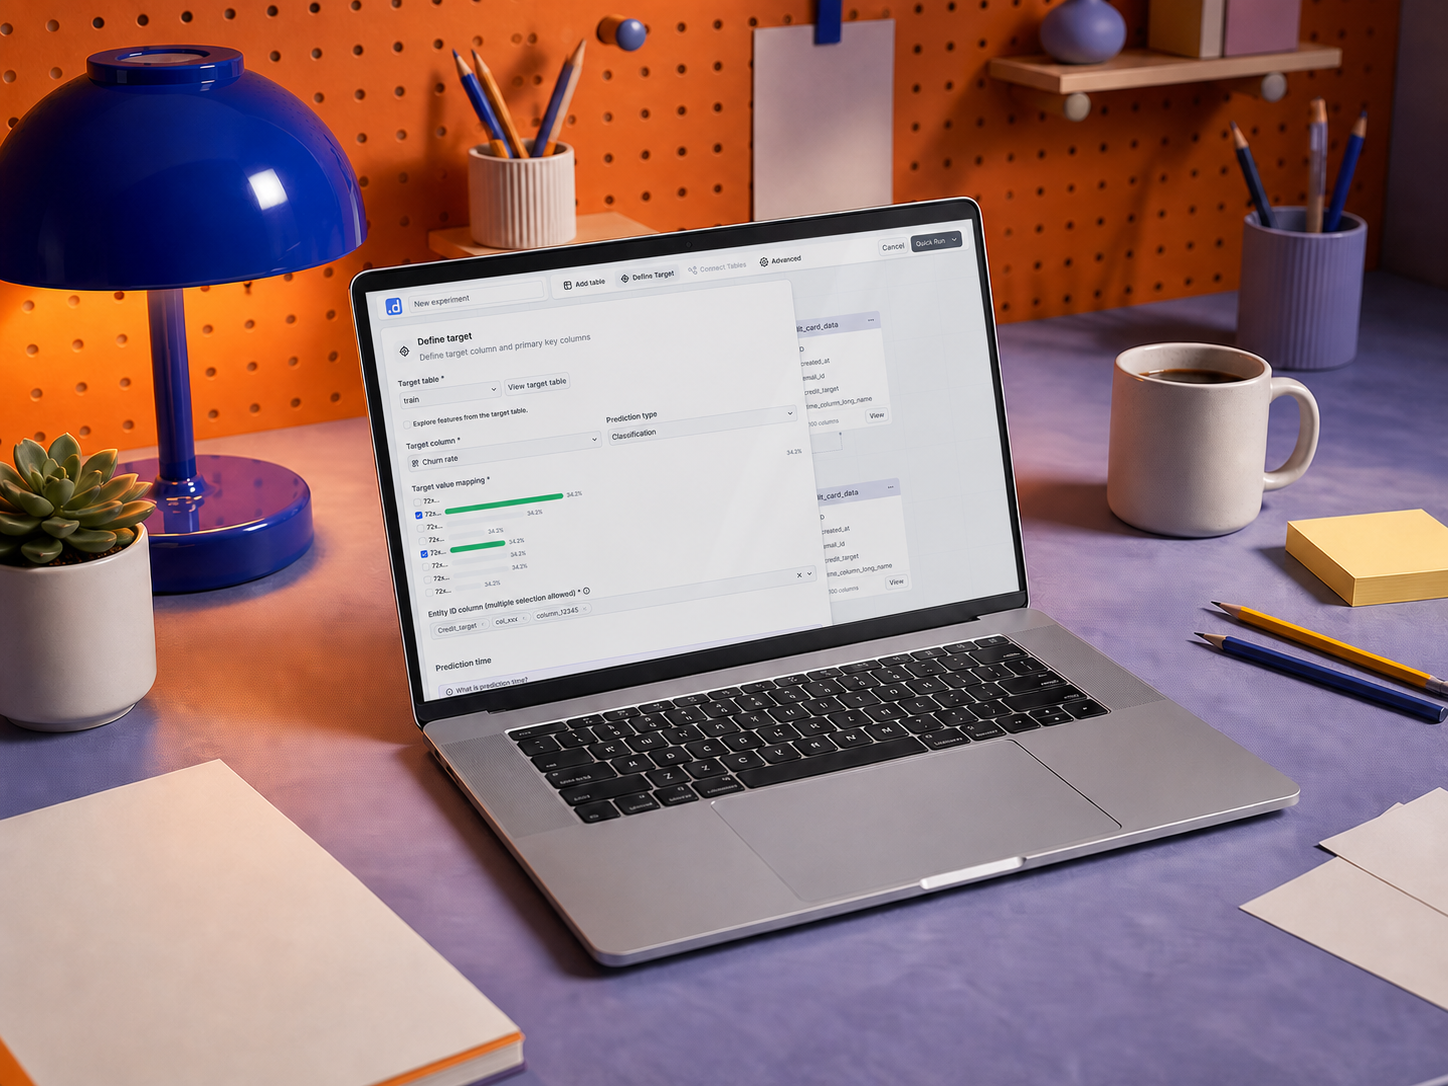
Defining a prediction target in the redesigned AutoML setup: target table, target column, and value mapping in one panel.
Summary
dotData Enterprise is an AutoML platform for business analysts with limited data-science expertise. I redesigned the configuration workflow so they could create and iterate on prediction tasks themselves — reducing reliance on the Data Science team, and making post-training adoption possible.
Trained analysts still could not create a prediction task
Setting up a prediction task was split across data sources, use-case setup, and model configuration. People could finish training, then still could not run a task on their own.
Workflow friction was limiting adoption
Low post-training adoption
Fewer than 5 of 50+ trained users created a prediction task independently after training.
High dependency on expert support
4 of 7 existing customers needed ongoing Data Science support; 2 customers had no active users.
Friction concentrated early in the workflow
Japan CS support tickets from 2022–2023 showed data preparation and task creation accounted for 60% of all feedback (44 of 73 items).
Unclear actions, unfamiliar terms, and errors that arrived too late
To find where people got stuck, I interviewed four data scientists on the US team. They supported the seven existing customers directly — acting as customer support — so they were the closest proxy for how the product was actually used. Each conversation walked a customer’s pain points, how the DS team currently worked around the setup, and where a business analyst still needed them to step in.
Separately, I analyzed customer feedback Japan CS had logged as support tickets from 2022 to 2023. 60% of that feedback (44 of 73 items) sat in data preparation and task creation. Three struggles showed up again and again.
Unclear actions
People could not tell what to do next. “The upload and import buttons are confusing. I don’t know what’s my next step.”
Unfamiliar terminology
Data-science language appeared before they had a first successful run. “What does using the target as a source mean? How does it affect the task?”
Feedback came too late
Mistakes only showed up after an experiment ran. “I want to see a warning when I make a mistake while connecting tables.”
Three disconnected pages hid the cost of every decision
The issue was not simply that setup happened across three pages. Each page asked Business Analysts to make a data decision without enough context to understand its downstream effect. They could not see how target selection, table relationships, and time settings worked together; they learned about invalid choices only after a run; and advanced controls appeared before they had built a working mental model.
The design challenge was to make a technically connected workflow understandable and recoverable without hiding the controls people needed to trust their model setup.
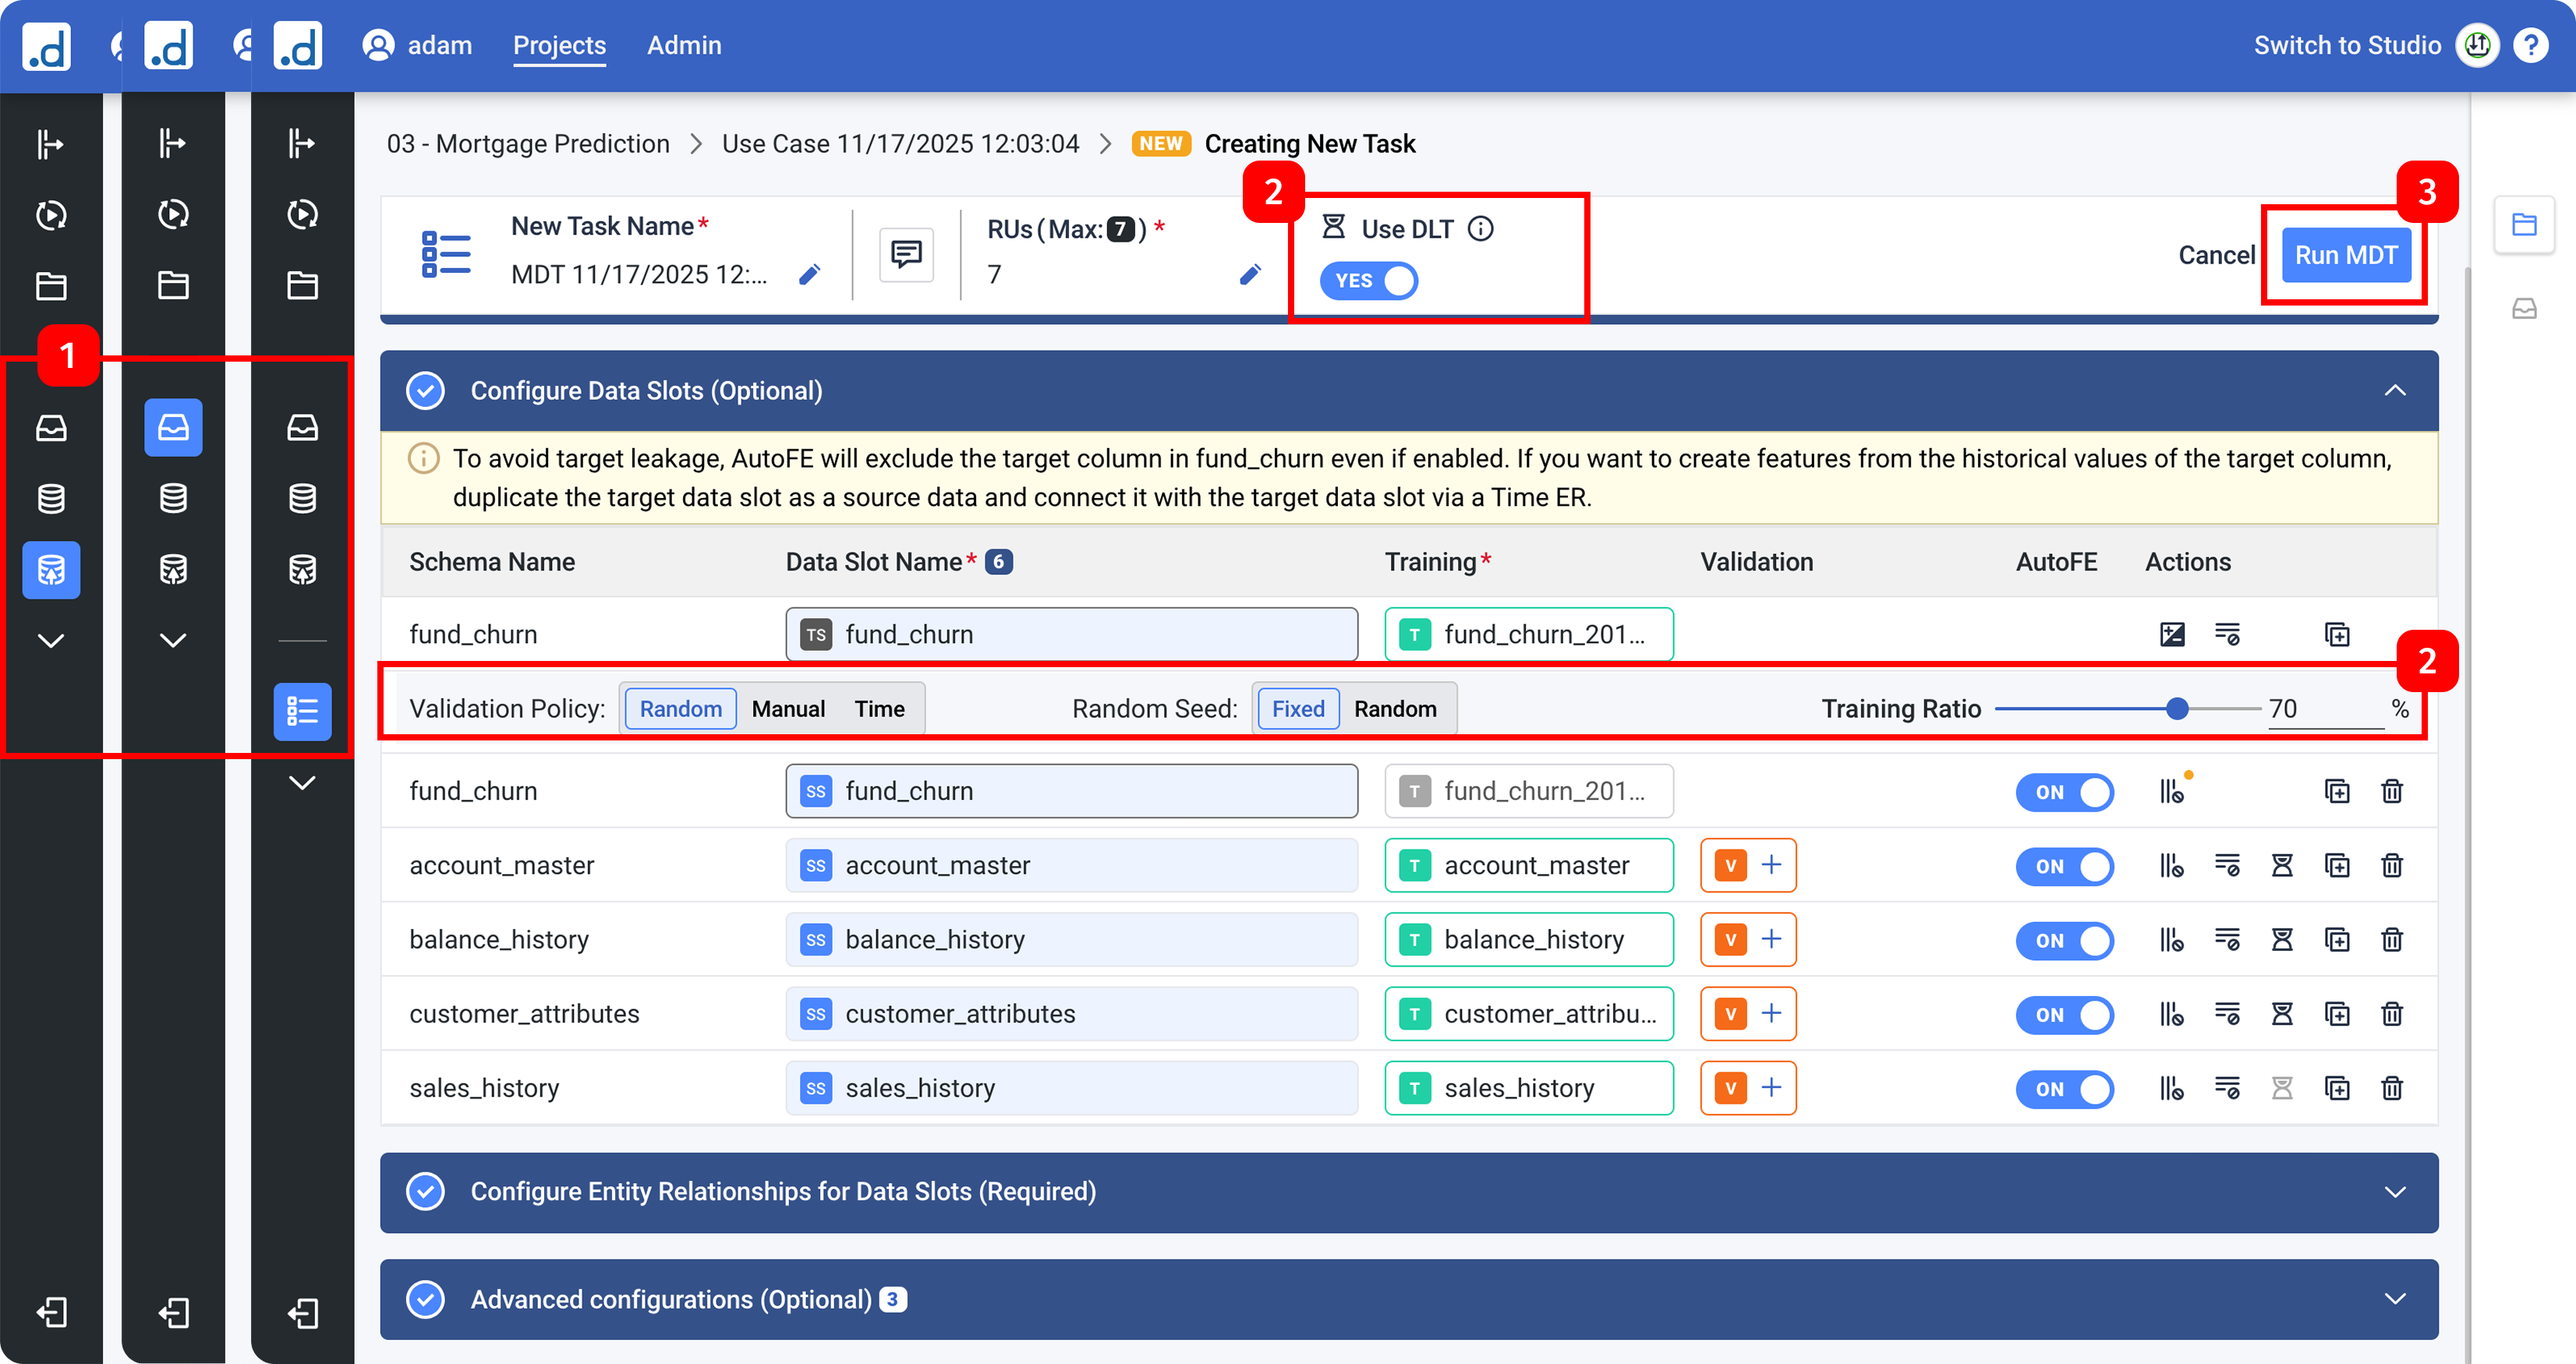
The existing task-creation screen, annotated to the three structural failures below.
Configuration was fragmented across three dense pages
Users had to configure data, targets, and relationships in separate views, without seeing how those decisions affected one another.
Errors surfaced after running an experiment
There was no way to validate the setup incrementally, so every iteration was expensive.
Advanced configuration appeared too early
Unfamiliar terminology and advanced settings showed up before anyone could complete a first experiment.
Put the training table at the center of the experience
Two decisions shaped the system. I started from how users think about the work, not how the pipeline processes it.
Every wizard step was configuring the same flat training table. So I asked: why isn’t that table the center of the experience?
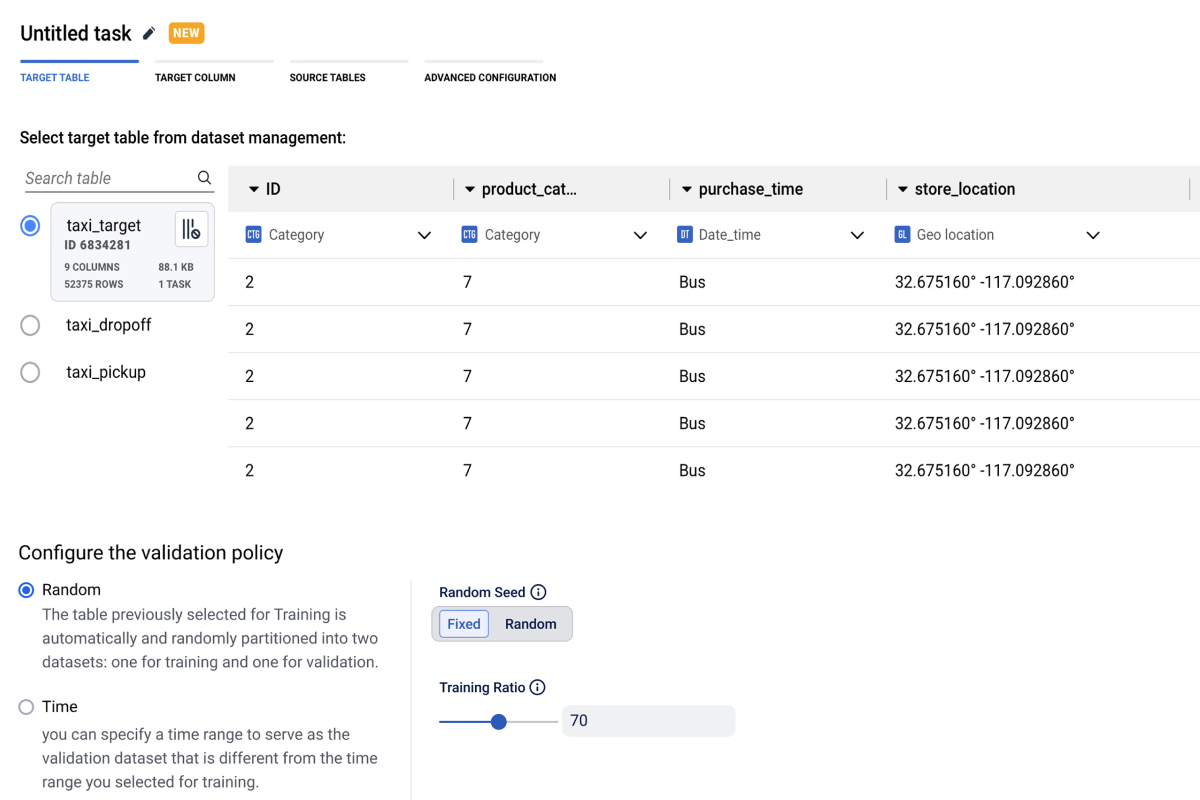
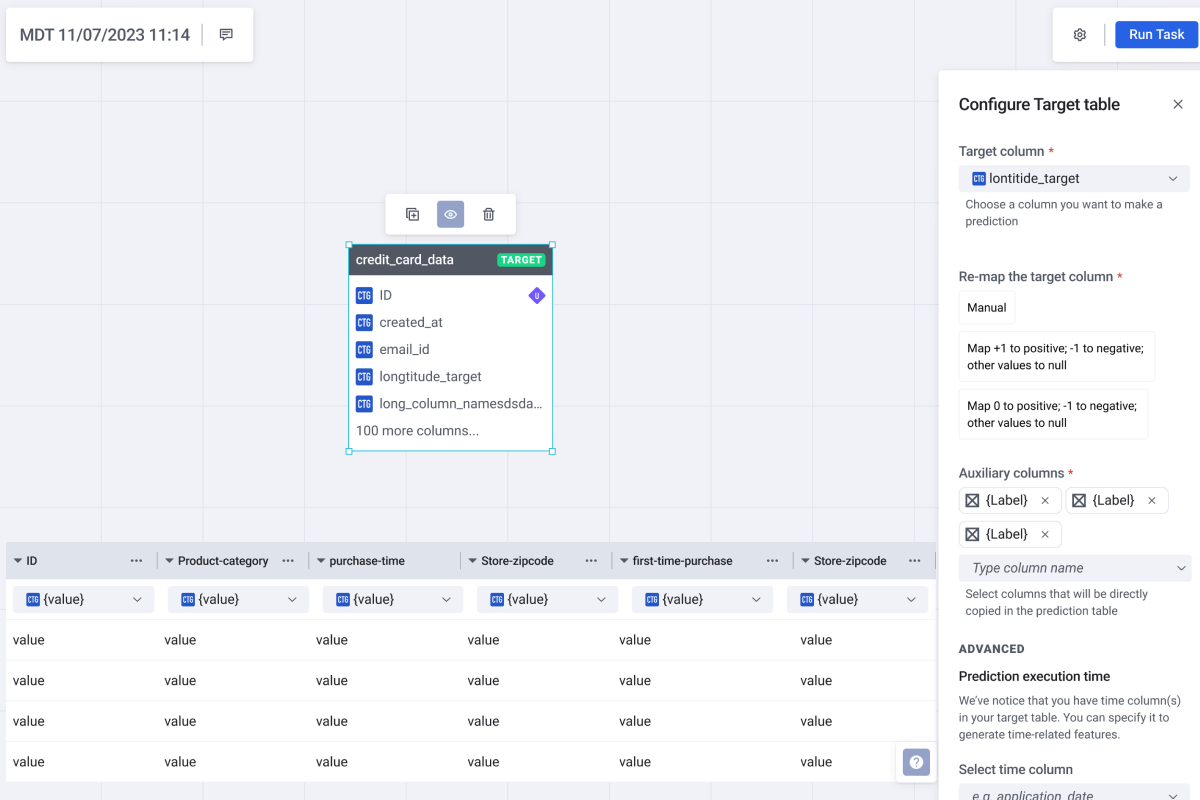
A wizard was faster for a first-time, linear path — but it hid relationships, and a mistake meant starting over. The canvas was chosen because it matches how users think about the task: the table is the object, and relationships stay visible while they configure, validate, and come back.
How much table context is enough?
One of the main challenges was how to add tables to the canvas easily, but with enough context. I tried several versions to find the least context people still needed to pick the right table.
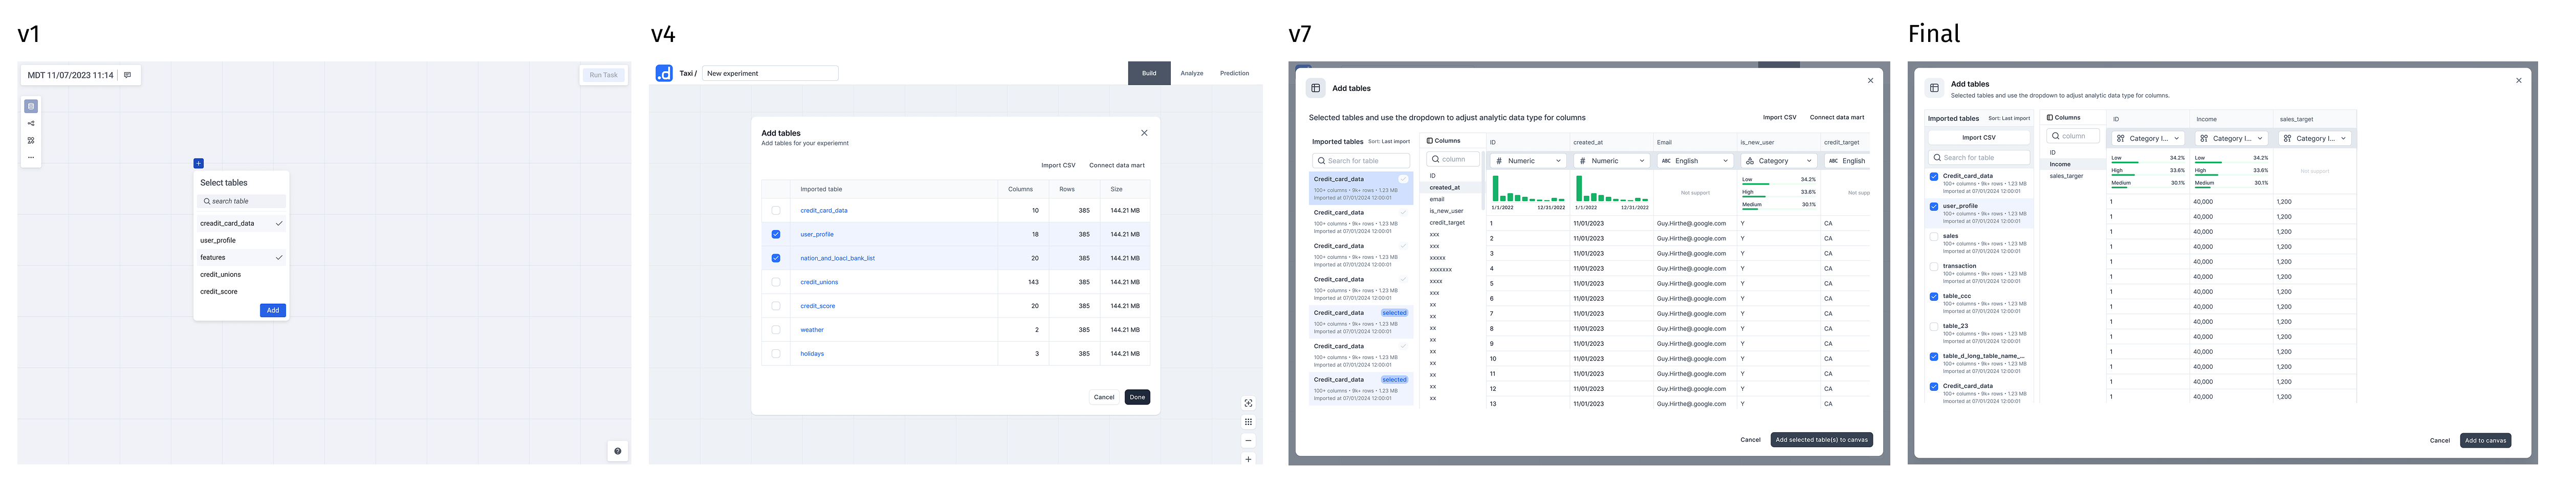
v1 name only → v4 list → v7 list + preview → Final combine. The range I was deciding across, not the only mocks.
Name only
v1. Lowest noise, but users could not judge whether they had the right table.
Name plus selected fields, click to preview
v4. Extra context, but the sample data still sat one click away — easy to skip when someone was already unsure of the next step.
Combine selection and preview
Final, shipped. Choosing a table and seeing its schema and sample data happened together, so people could confirm they had the right data before they connected anything.
One canvas, four interactions that made it self-serve
The canvas is the container. These four interactions are what made it usable for non-experts.

The same decisions on one surface — three separate setup workflows became a single flow users can move through, validate, and return to.
A guided, end-to-end task-creation flow
One surface takes people from selecting tables to a runnable experiment. Next actions stay obvious; later steps stay in view instead of locked behind a wizard.
Walking the full setup on one canvas, from adding tables to a runnable experiment.
Pre-run validation and recovery
Running an experiment first checks the setup. If something is wrong, execution stops and the UI names the fix — not a failure after compute.
Validation names what is missing and offers the action that fixes it, instead of failing at run time.
Jump to the configuration that needs changing
After a run, users open the exact setting they want to revise instead of clicking through every step again.
Opening a table relationship from the canvas and editing it in place.
Contextual configuration panels
Each decision appears where it is meaningful — target definition, table relationships, or advanced time controls — with defaults and inline explanation instead of one giant form.
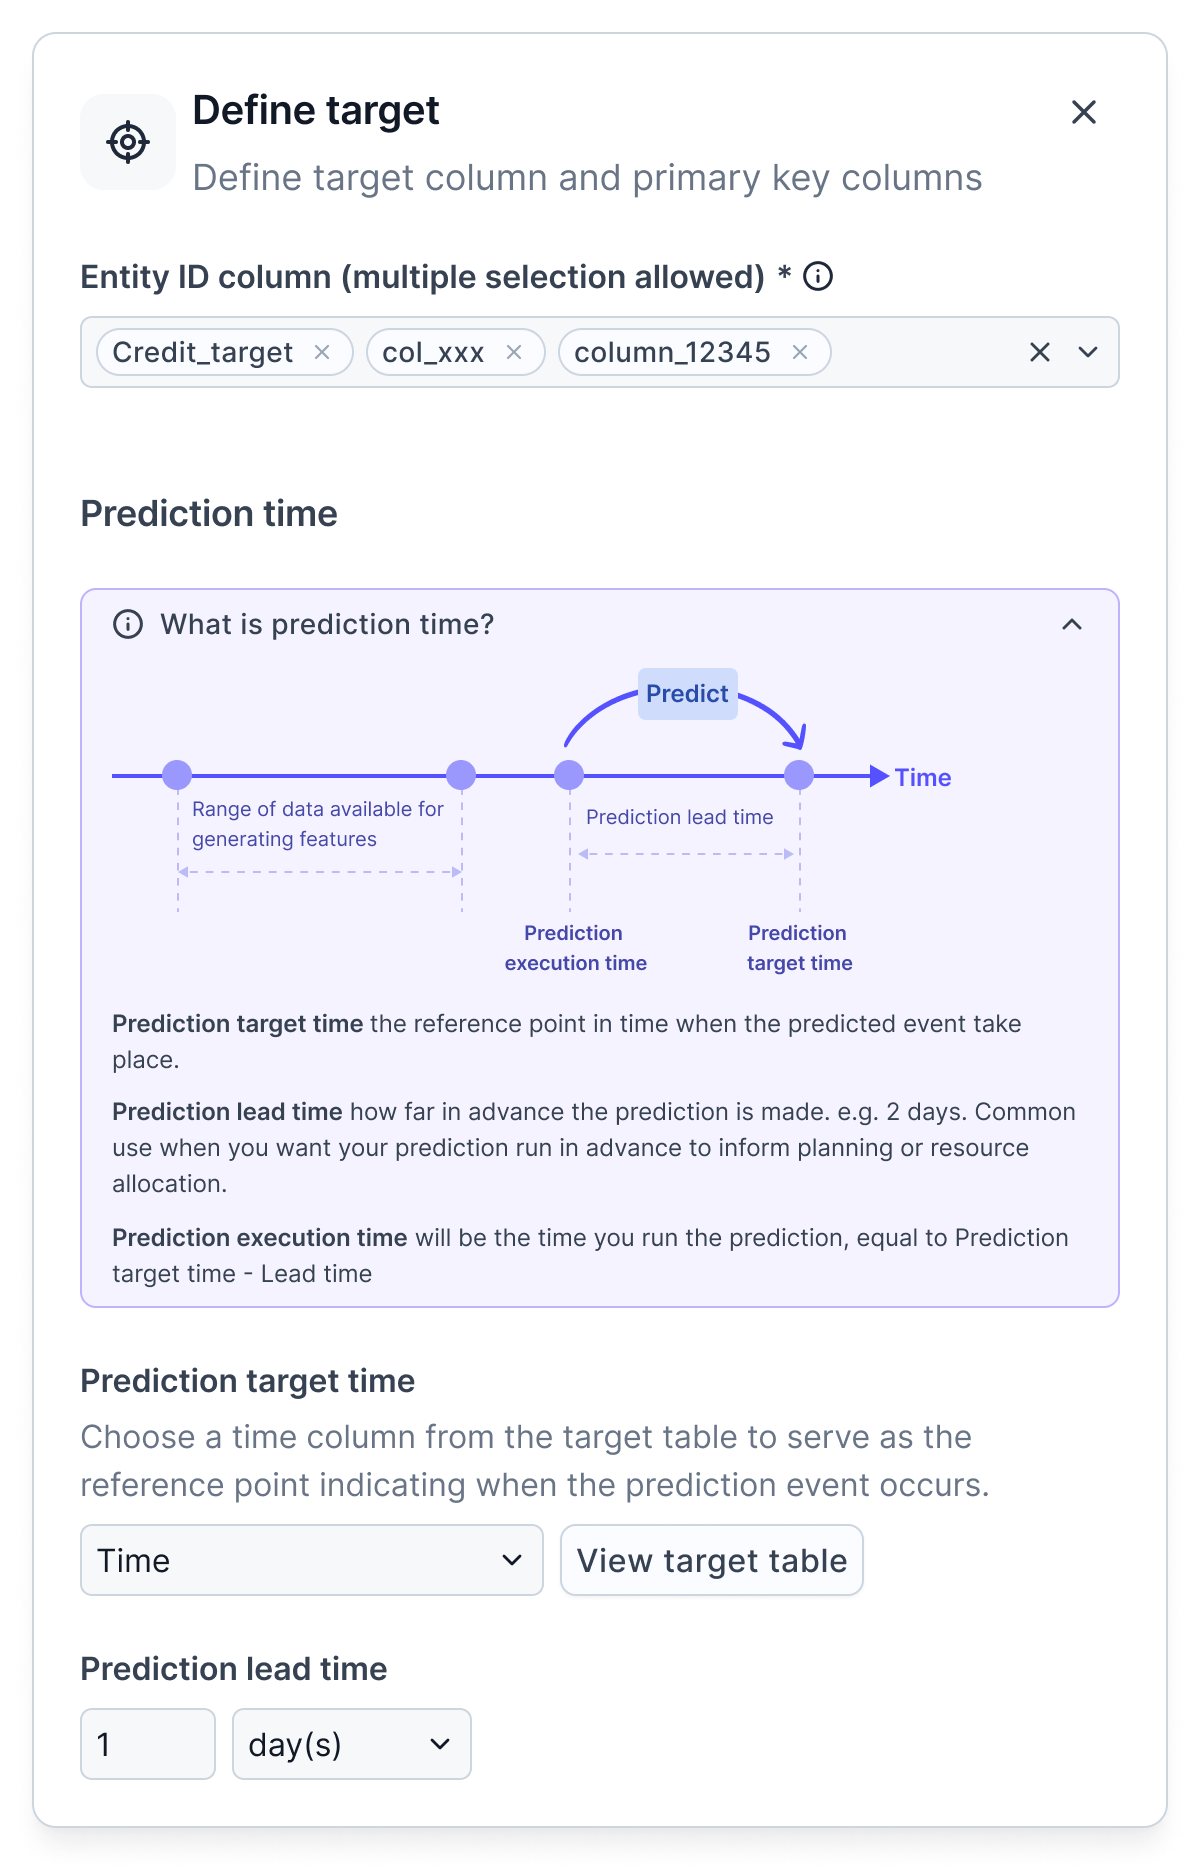
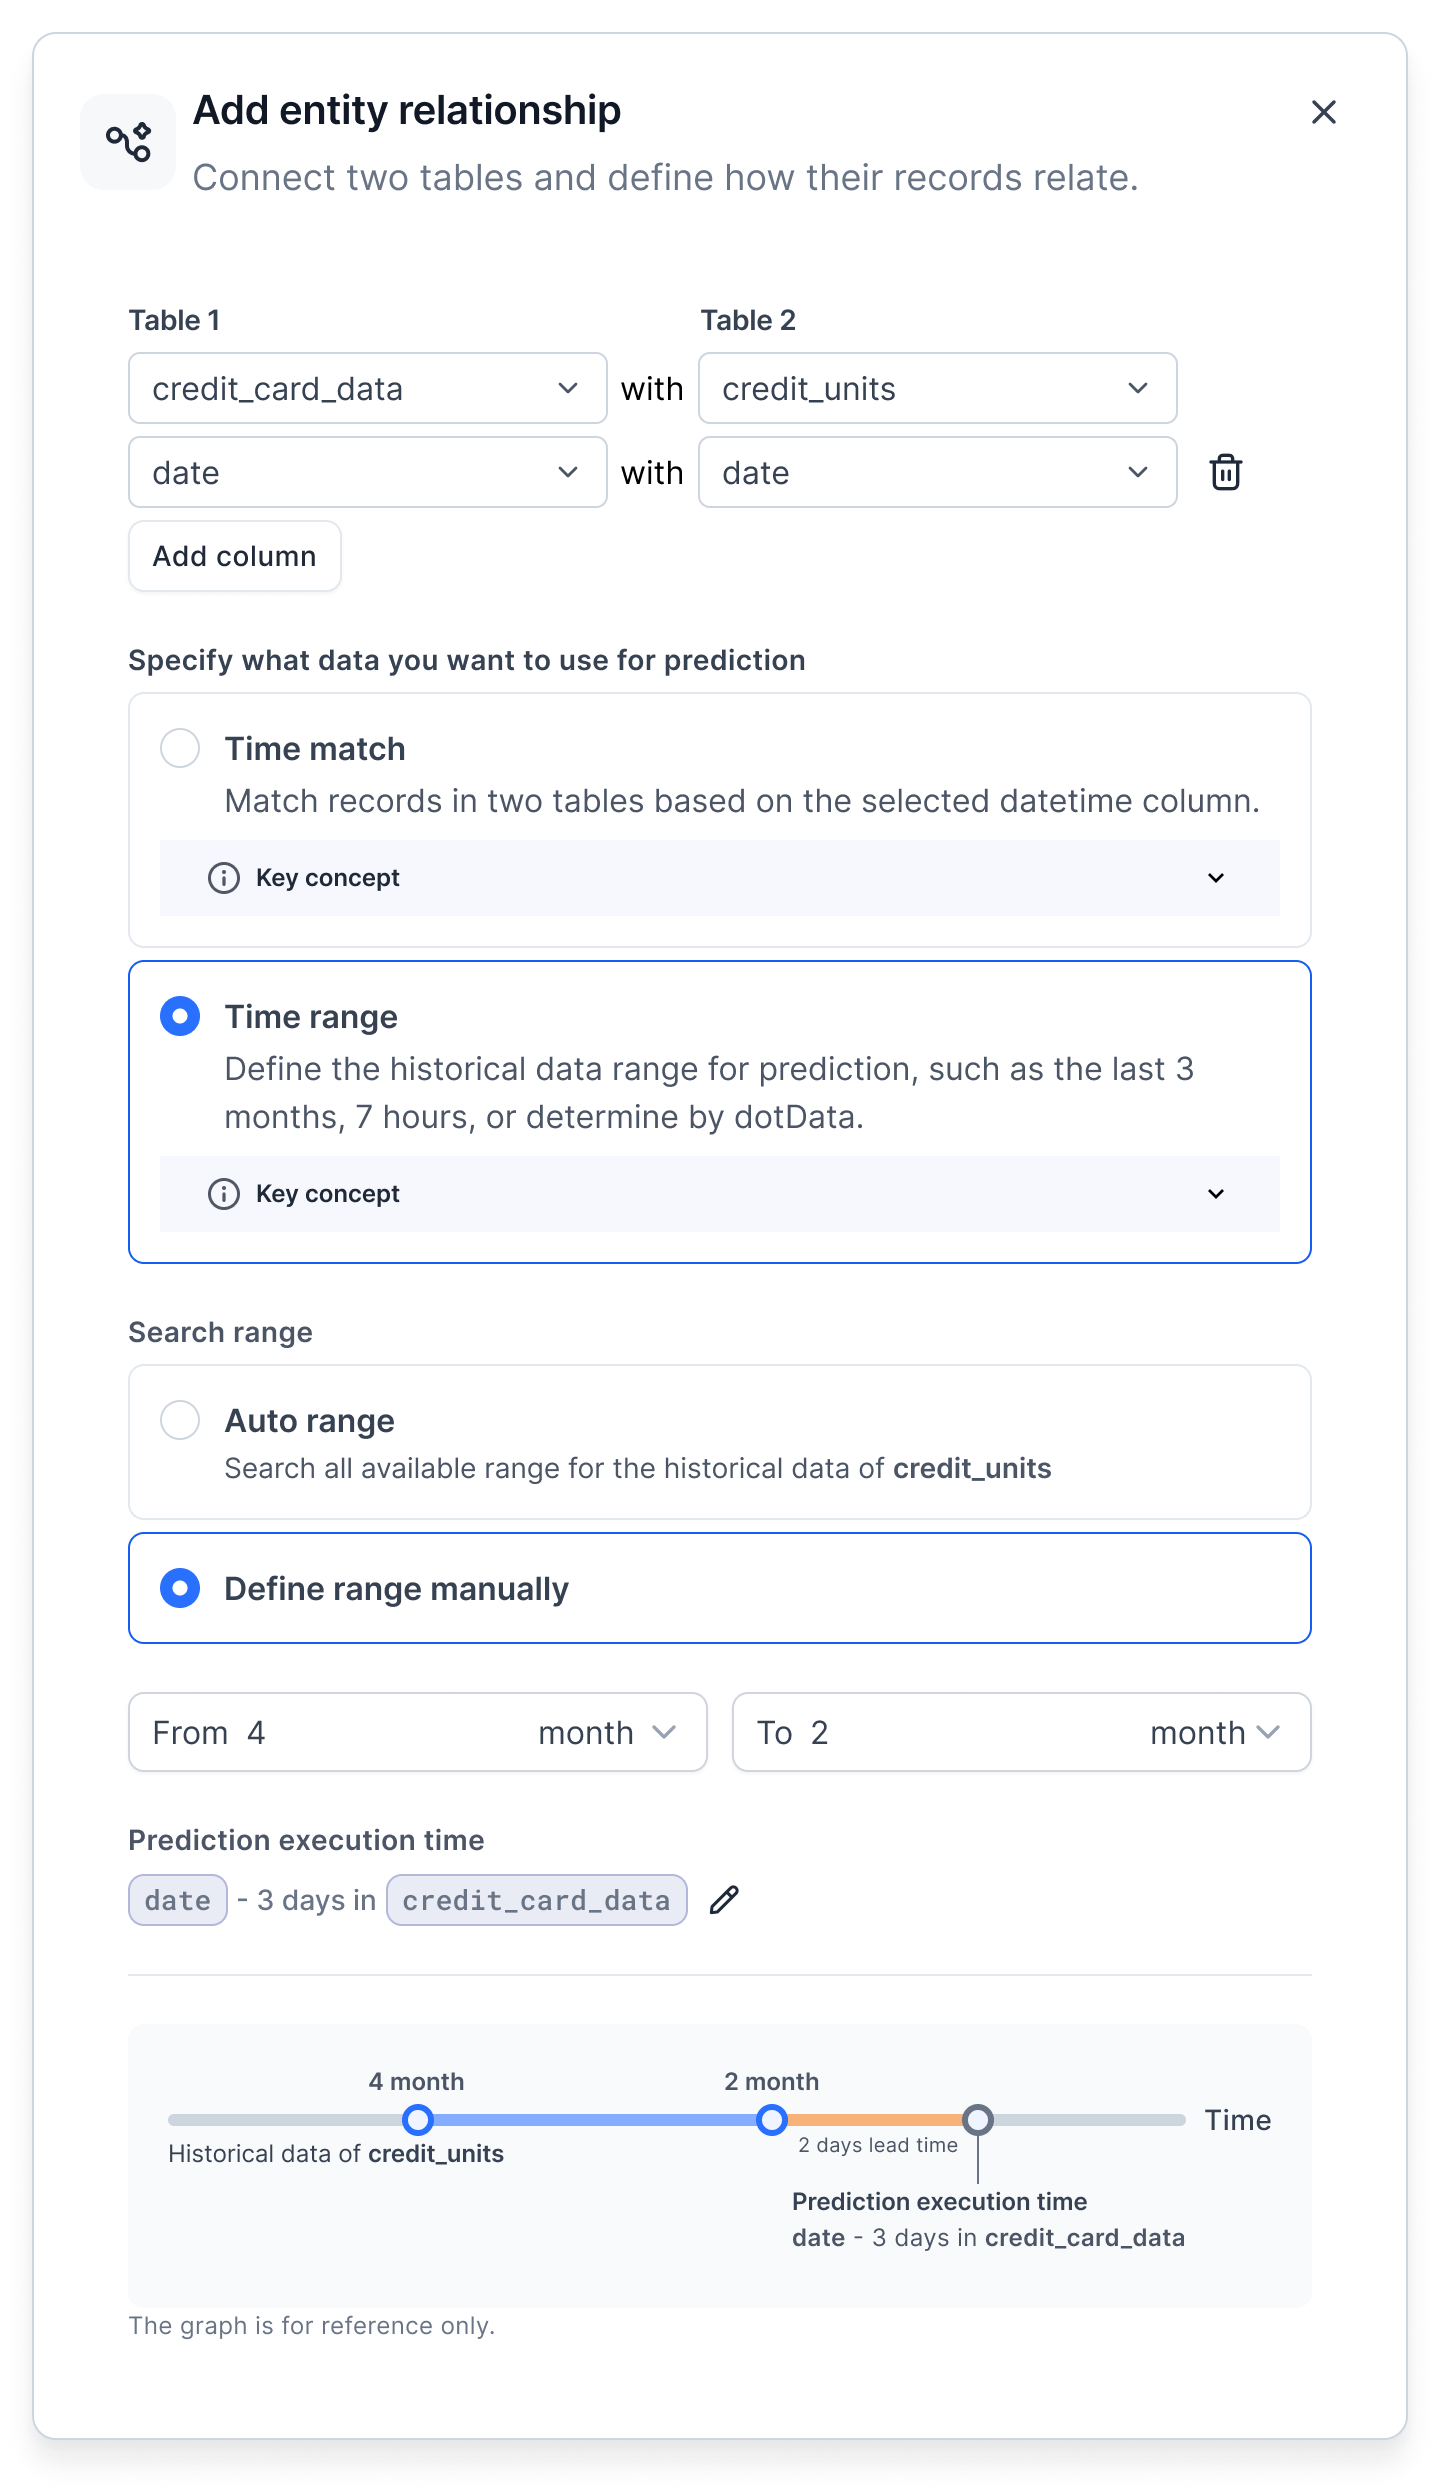
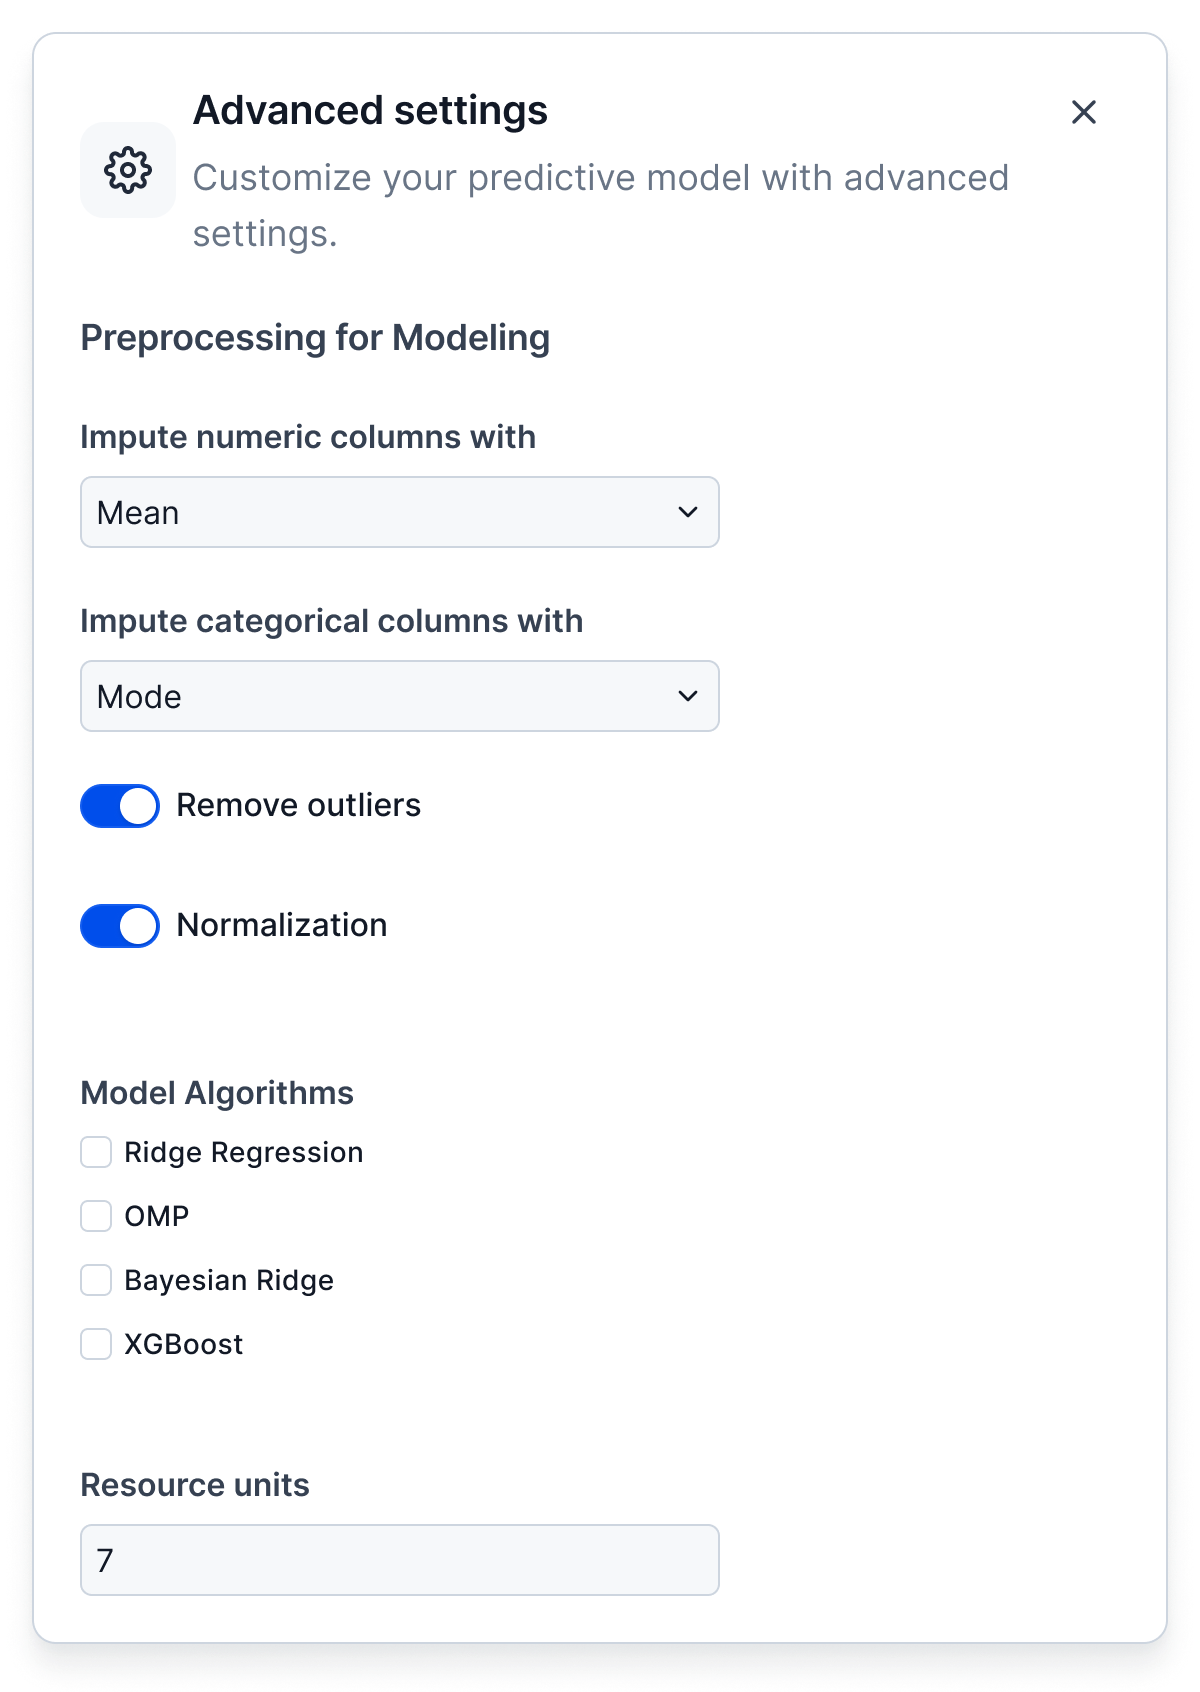

The result: target, source tables, and their relationships stay visible while the model is configured, run, and adjusted.
Recurring workflow behaviors became shared patterns
I extracted list selection, table-card states (default / selected / target / error), and actionable feedback (required / warning / recommended). Those patterns later fed the product design system.
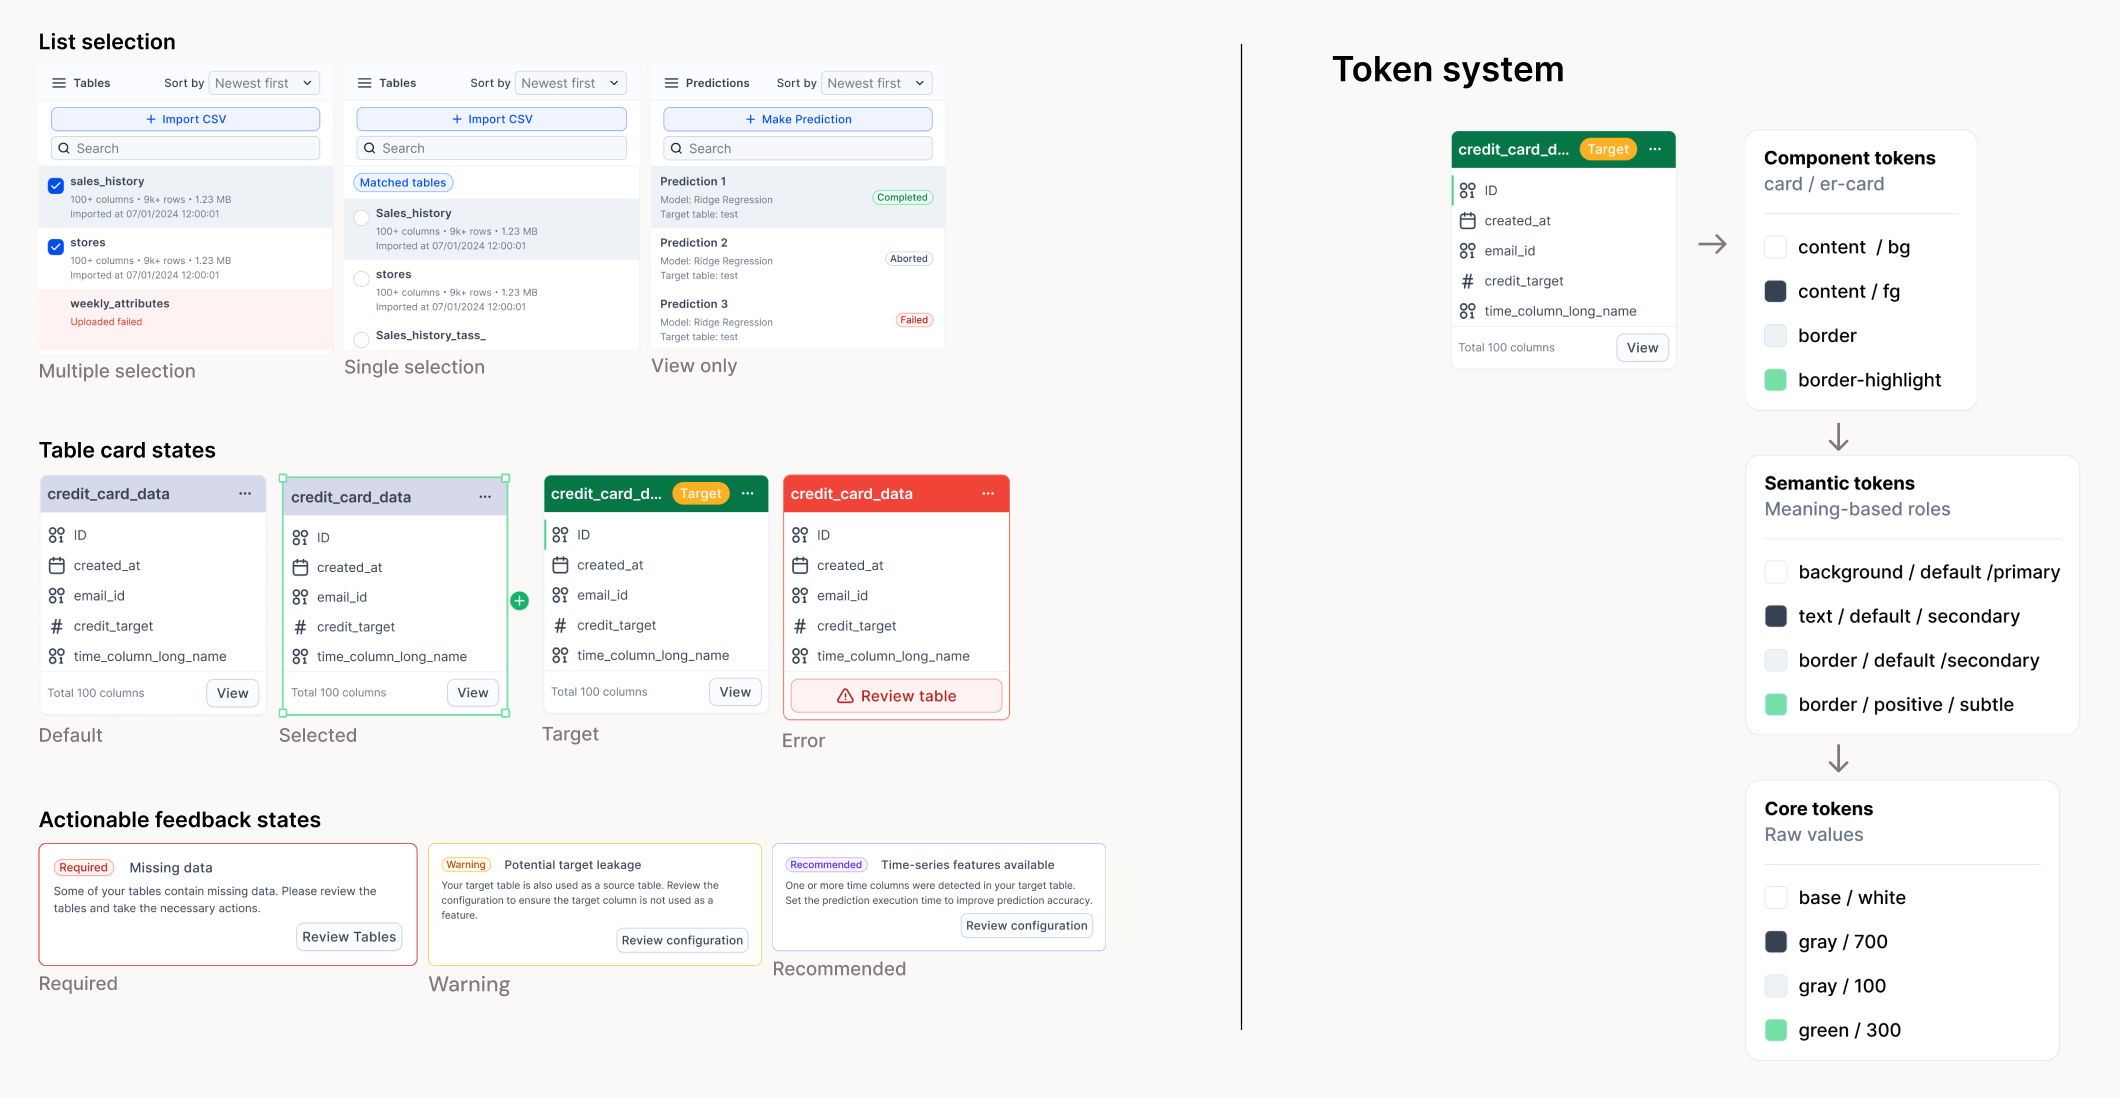
Selection, table-card, and feedback states, mapped onto the token system used across the product.
From 20+ configuration actions to 5 guided steps
What changed
Fewer configuration actions
Reduced 20+ configuration actions to 5 guided steps.
Faster iteration
Users could revise one setting and rerun, instead of rebuilding the setup.
Clearer decisions
Each choice sat next to the table it affected.
What I will measure after customers upgrade
- Task completion rate
- Support requests per customer
- Time to first successful experiment
Involving engineering early made the canvas possible
This was a highly collaborative project. Bringing engineering in early mattered in both directions.
Align on the pain before the solution
Sharing research findings early meant we agreed on the user problems — unclear next steps, unfamiliar terms, errors after the run — before anyone committed to a layout.
Learn the limits and the possibilities in time to change course
Knowing technical constraints and what was newly possible let me adjust the design quickly, instead of discovering a blocker in handoff.
Give engineering time to plan the hard change
The canvas was a large architectural shift. Early alignment let engineers plan for it, rather than treating it as a late UI request.
Ship one flow in slices
This stayed one configuration flow. We did not wait for a perfect canvas: concept and workshop first, then an internal MVP broken into features, then ticketed iteration, then a customer-upgrade release.