- Project
- In a Nutshell Books
- Role
- End-to-end product designer and builder
- Timeline
- 3 months
- Scope
- Product strategy, UX/UI, content model, research workflow, frontend, backend, database, and AI workflows
- Tools
- Cursor, Claude Code, Claude, Gemini, NotebookLM, Supabase, Vercel, GitHub
Designing a human-in-the-loop AI content workflow
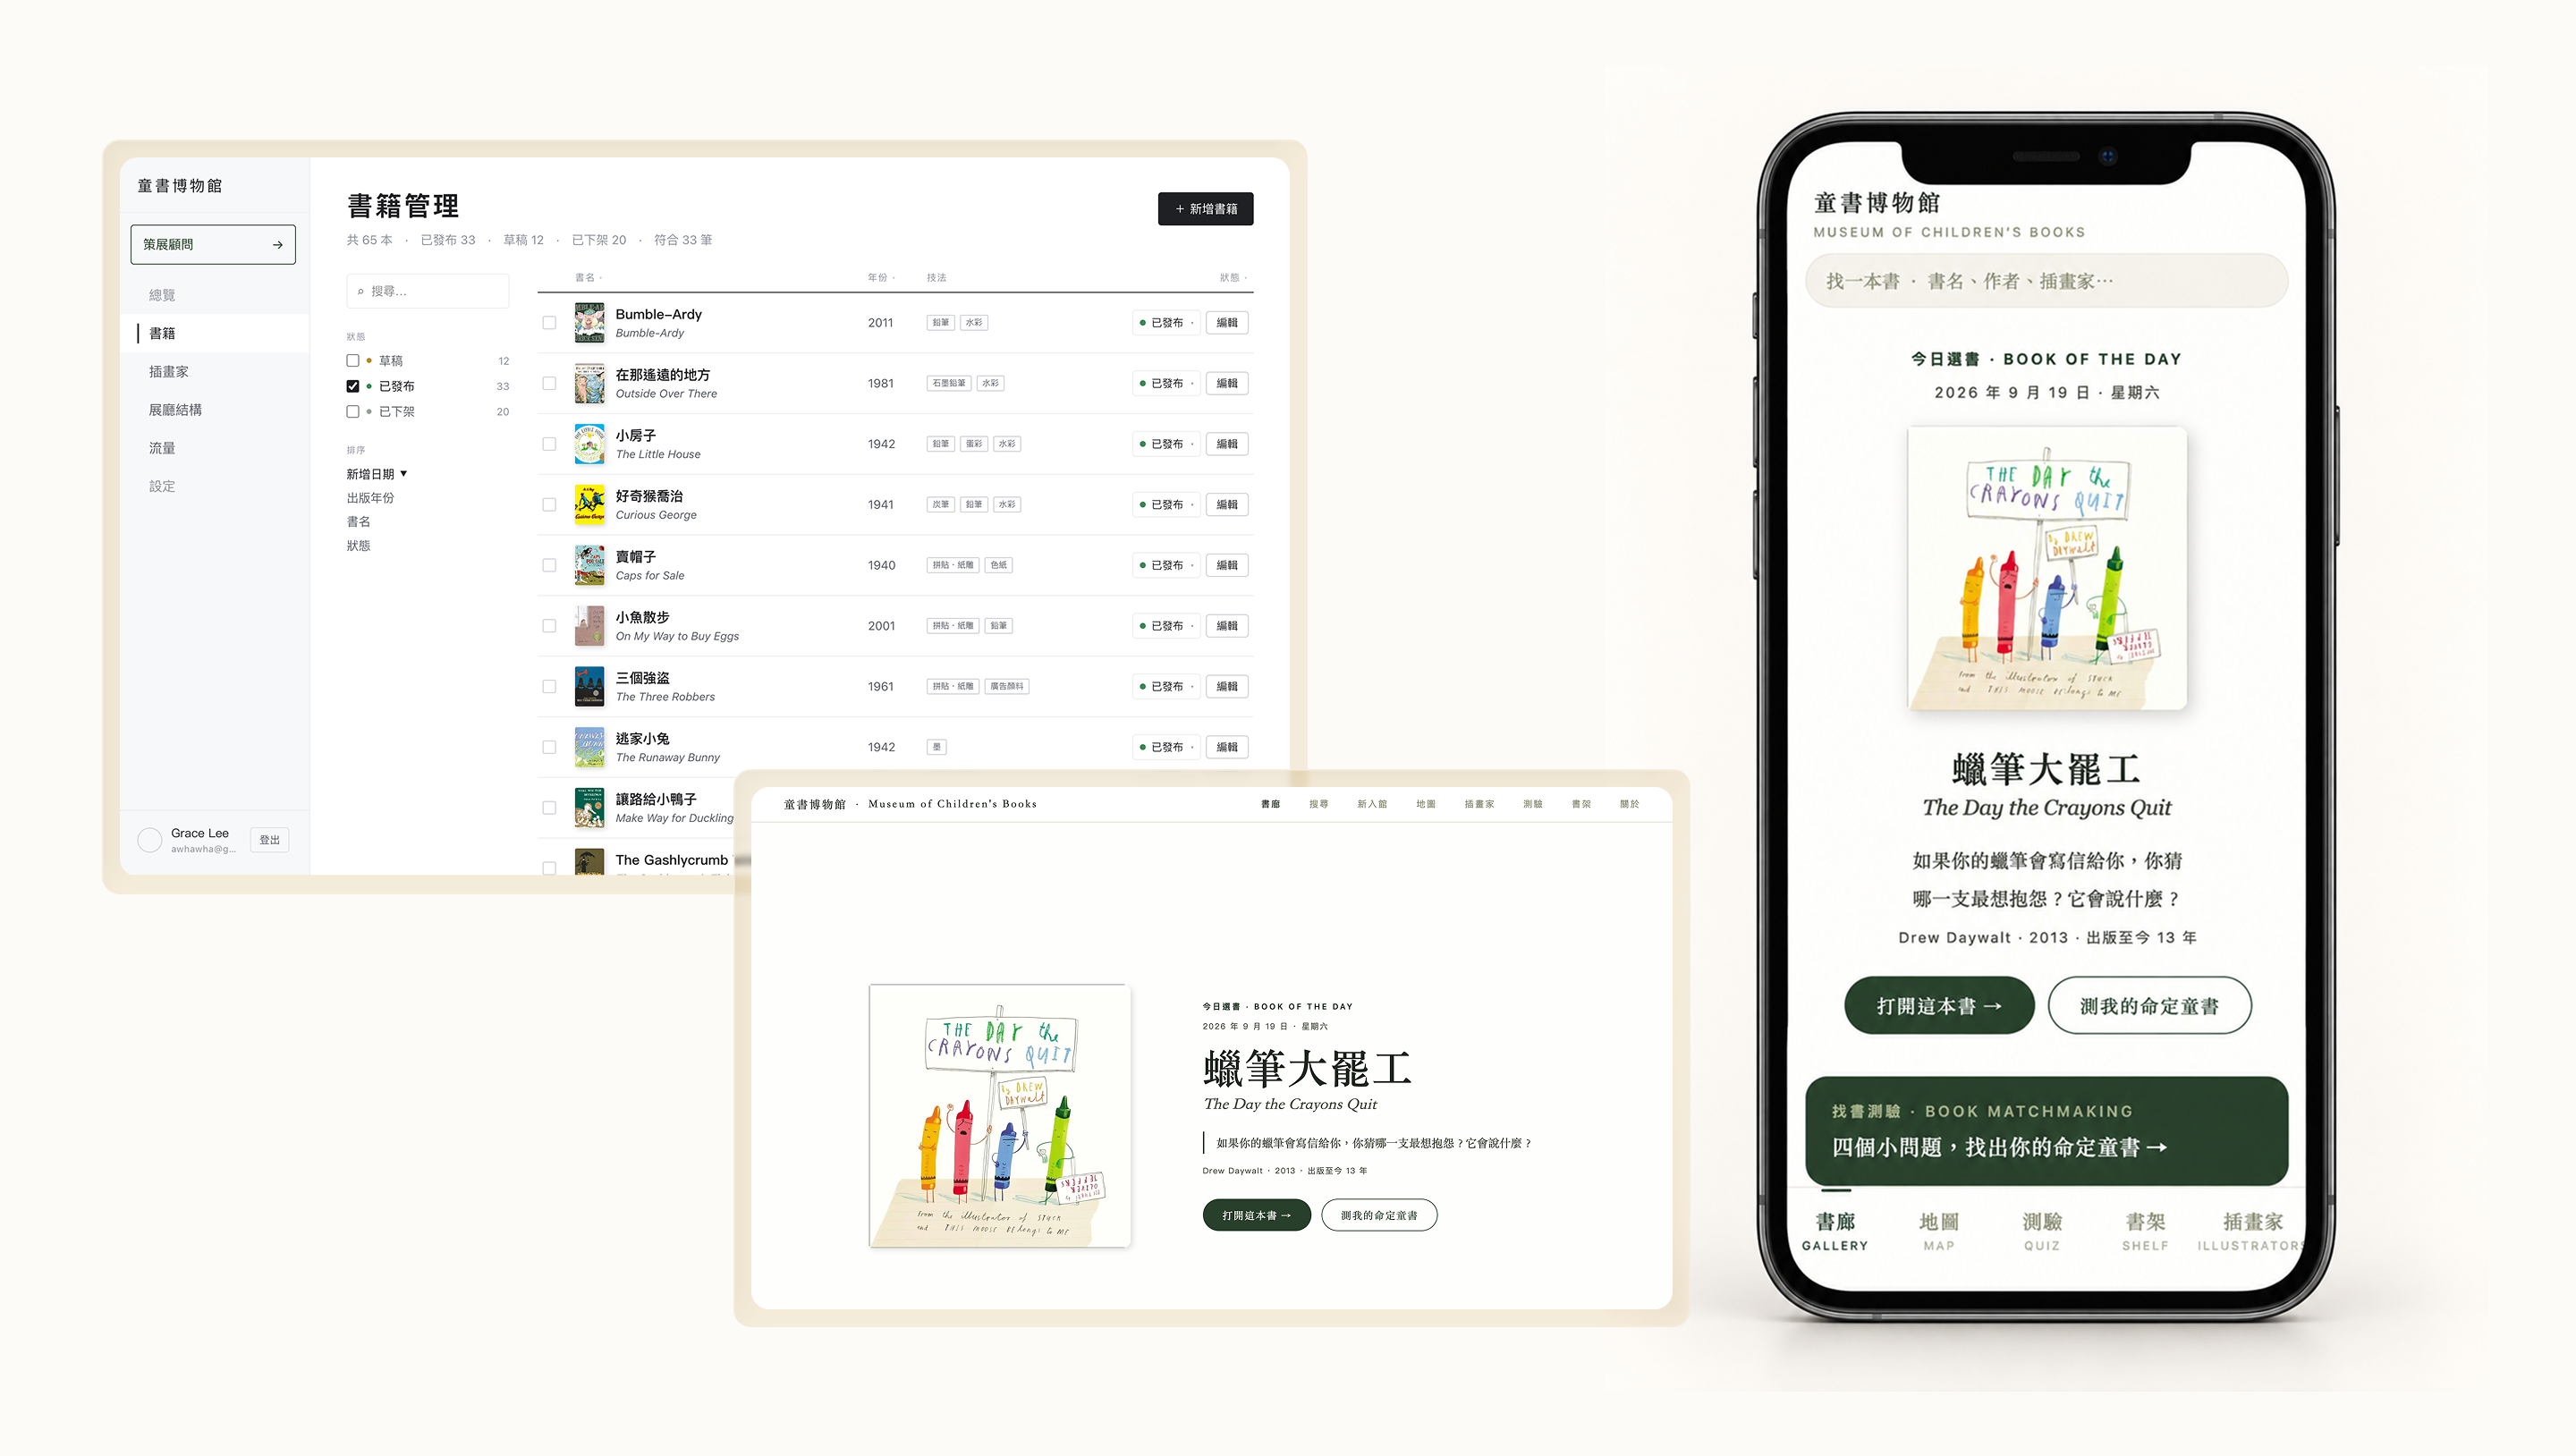
The public museum beside the collection admin: Book of the Day on the site, and the book records behind it.
Summary
In a Nutshell Books is a living personal museum of children’s books. It began after my daughter was born and I started collecting picture books—not only as books to read together, but as objects of illustration, visual storytelling, and creative practice.
Most available book reviews are written for parents and focus on what children can learn. I wanted a different kind of resource: one that could help me understand why an illustrator made particular choices, how a book’s visual language works, and what makes it worth returning to.
Over three months, I designed and built a bilingual collection experience that now includes 65 books, 32 illustrators, and 7 emerging exhibition rooms. As the collection grew, the project evolved from a public-facing museum into an AI-assisted workflow for researching, analyzing, and curating new acquisitions.
Researching one picture book deeply is slow and fragmented
I used web search, author interviews, publisher pages, museum archives, book reviews, and tools like ChatGPT and NotebookLM. The outputs were often interesting, but difficult to trust, inconsistent in depth, and disconnected from the rest of my collection. I also had to repeatedly copy information between tools and manually check whether a suggested book already existed in the museum.
Two opportunities
- A public experience: create a better way to browse, read, and return to a growing collection.
- A research workflow: turn behind-the-scenes research and acquisition work into a more reliable AI-assisted process.
Building the museum before adding AI
I first focused on the collection experience: browsing books, discovering recent acquisitions, finding illustrators, and reading visual analysis in a format that feels editorial rather than instructional.
As the collection grew, I changed the information architecture in response to my own use.
From a timeline to a searchable collection
A chronological view was attractive at first, but it did not scale with a collection designed to keep growing. I moved toward browsing and search patterns that support discovery across books, illustrators, and exhibition contexts.
From a split analysis layout to a long-form reading experience
Early AI-generated analyses were short and generic, so a two-column layout felt sufficient. Once I developed deeper, sourced analysis, the content needed more room. I redesigned the book page with a focused hero and a longer editorial reading flow beneath it.
The public museum gave the AI workflows a real destination: research was no longer an isolated answer in a chat window; it became material that could be reviewed, structured, and preserved in the collection.

The public reading surface: a focused book hero, then room underneath for a longer editorial analysis.
Designing a research workflow that earns trust
My first attempt was an “AI generate” button in the editor. It could fill factual fields reasonably well, but it produced vague analysis and made it hard to tell which claims were grounded in evidence.
I tried NotebookLM next. The output quality improved when I supplied source material, but the research setup had to be repeated for every book.
The first attempt: an AI generate control in the editor. Factual fields filled in; the analysis stayed vague.

NotebookLM improved the writing when I supplied sources, but the setup had to be repeated for every book.
A reusable /new-book skill
The final approach was a reusable /new-book skill. Its goal is not to make every book page sound complete. Its goal is to build a trustworthy draft that a curator can review.
The workflow
Match voice, not facts
The workflow reads my existing writing to align with the museum’s editorial voice. These examples guide tone only; they are never treated as factual evidence.
Search existing research first
It searches my research notes using the Chinese title, English title, author, and illustrator. Existing observations are given priority.
Research with an explicit source hierarchy
It prioritizes author interviews, official publishers, museums, research institutions, and award organizations. Retail pages and Wikipedia may support basic bibliographic details, but not analysis or claims about artistic intention.
Ground every factual claim
Each factual statement added to a draft keeps a source URL. If sources conflict, the workflow marks the item as uncertain instead of choosing a convenient answer.
Avoid invented visual analysis
If I have not seen a book’s interior pages, the system does not describe a specific spread, composition, or colour decision. If an image resembles a technique, it uses effect-based language rather than claiming an unverified production method.
Check for duplicates before creating a record
The workflow checks the authenticated collection database, including drafts and unpublished books. If a record already exists, it updates that draft instead of producing a duplicate.
Keep a human approval step
The output is a draft, not a published page. I review it before the book enters the museum.
This changed my relationship with AI. Instead of asking it to write an authoritative interpretation, I designed it to reveal evidence, preserve uncertainty, and make a repeatable research process easier to review.
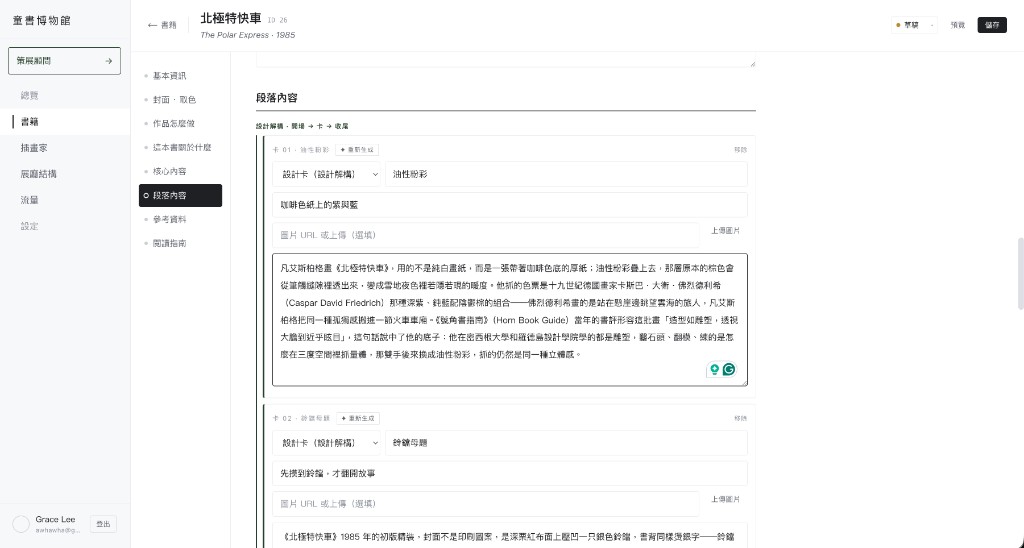
The output of the workflow: a draft in the admin, still unpublished, waiting for a curator to review it.
From a thin recommendation to a grounded book record
When I asked the Curatorial Advisor to recommend books similar to Leo Lionni, it returned titles connected by broad stylistic language such as “bright colours” or “cut-paper collage.”
That was not enough. A collector does not only need to know whether a book resembles another book; they need to know why it belongs in this particular collection.
For example, the workflow for Have You Seen My Duckling? identified that an existing draft already existed, corrected the Chinese title, avoided creating an unsupported illustrator record, and prepared a sourced research draft rather than pretending to know unverified details.
Distinctions it preserved
- It did not claim to have seen specific interior spreads when it had not.
- It did not label a material when the source terminology did not match the museum’s taxonomy.
- It used the official Caldecott record when it conflicted with an autobiographical date.
- It separated documented author intent from visual interpretation.
The result was not merely a richer page. It was a research trail that could be reviewed, edited, and retained with the collection.
Designing the Curatorial Advisor
The Curatorial Advisor helps identify books to consider for the museum and adds selected titles to a review queue.
Its current interface lets me ask for recommendations, inspect brief rationales, select titles, and send them into a draft workflow. This was a meaningful improvement over searching across the web and manually copying suggestions into my database.
Building it exposed an important product limitation: the agent currently receives a thin, flat list of book records—title, year, author, category, and a one-sentence introduction—plus the current conversation. With this limited context, it can reliably identify surface similarities, but it cannot make a strong curatorial argument about what the museum is missing.
The next version should help the curator specify an acquisition lens—such as a missing medium, period, narrative device, illustrator lineage, or exhibition contrast—and show the rationale in a structured way.
What role could this book play in the collection?
Structured rationale
- What it connects to
- What gap it fills
- What it would add or challenge
- What evidence supports the recommendation
- What remains uncertain
What I have validated
A collection-first experience can make deeper picture-book research feel worth preserving.
Structured, sourced drafts are substantially more useful than one-off generated articles.
AI is most useful when it reduces research and duplicate-checking work without hiding uncertainty.
Human review is essential when writing about artistic intention, visual technique, and editorial interpretation.
This project is currently a self-directed, live prototype rather than a tested product for external users.
What I would validate next
Next
- Test the Curatorial Advisor with 3–5 picture-book collectors to learn how they define a meaningful “collection gap.”
- Add richer collection metadata and an explicit acquisition brief, so recommendations can be justified by curatorial value rather than stylistic similarity.
- Bring the research skill into the product workflow, so a curator does not need to switch between the website and an external coding environment.
- Test whether parents and collectors value the same forms of analysis, reading guidance, and discovery.
Reflection
This project taught me that AI-native product design is not about adding a chat interface to an existing workflow.
The harder and more valuable work is deciding what the system may claim, what evidence it needs, where uncertainty should remain visible, and when a person must make the final judgment. I designed In a Nutshell Books as both a museum and a working system: a place to discover children’s books, and a way to research and curate them with more care.